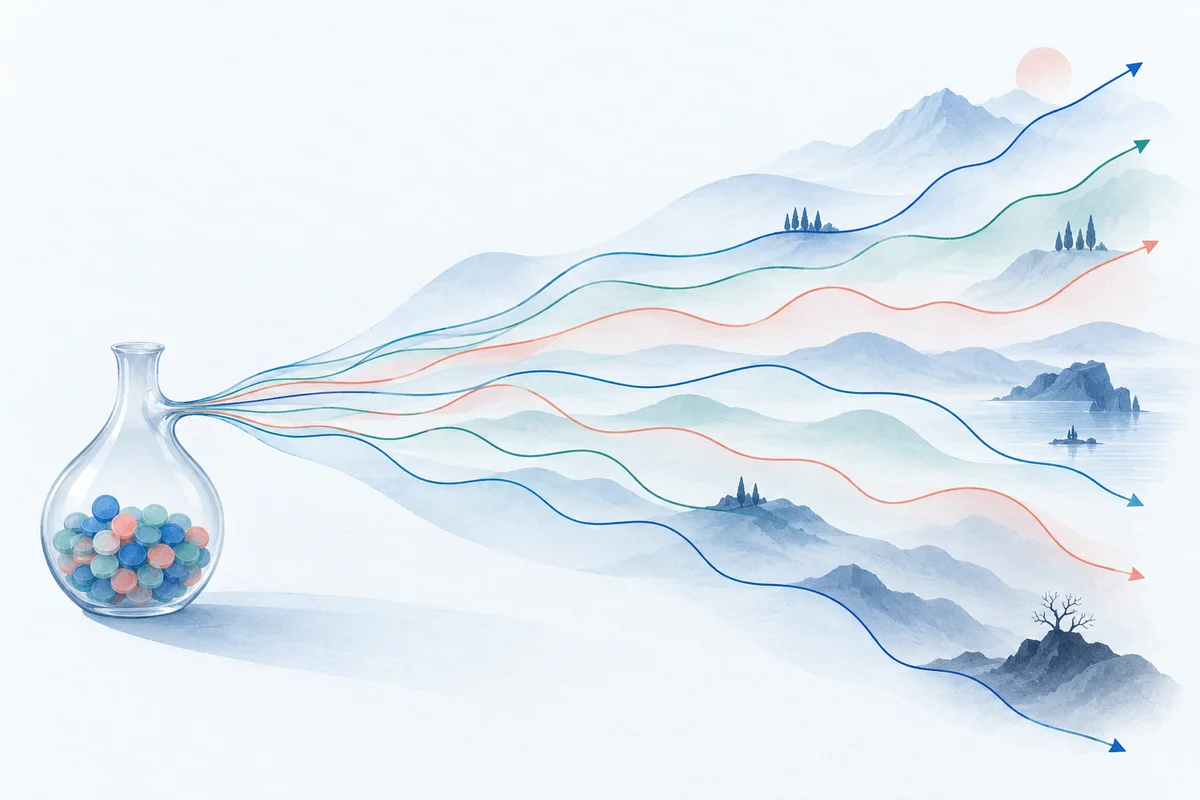
Why a single backtest curve is an illusion of certainty
When quants evaluate an algorithmic strategy, the first artifact inspected is almost always the cumulative equity curve. If that curve slopes smoothly upward with an attractive Sharpe ratio and a modest 12% maximum drawdown, the strategy is often declared ready for deployment.
However, a single backtest curve is an illusion of certainty. It represents merely one realized path drawn from an unobserved stochastic process.
The fundamental weakness of a solitary historical backtest is path dependency. Even when a strategy holds a genuine edge—such as a 55% win rate and a 1.4 profit factor—the sequence in which trades arrive determines whether the account flourishes or encounters ruin.
Consider two traders executing the identical set of 100 historical trades:
- Trader A (Dispersed Losses): Wins and losses alternate evenly. Peak-to-trough drawdown never exceeds 10%.
- Trader B (Clustered Losses): A streak of 12 consecutive losses strikes in month one. Because drawdown compounding is asymmetric—a 30% loss requires a 42.9% gain to break even, while a 50% loss requires 100%—Trader B suffers crippling capital impairment before the winning cluster arrives.
In live markets, capital is finite and margin constraints are binding. Severe early drawdowns force risk managers to slash allocations or trigger investor redemptions. Long before a strategy reverts to its theoretical expectancy, the account is closed.
A monte carlo backtest removes single-path bias. By permuting and resampling trade logs across thousands of counterfactual market sequences, it stress-tests strategy survival against sequencing risk and sample fragility.
Three Monte Carlo techniques for trade logs
Selecting the appropriate resampling method is critical. Applying an incorrect technique can destroy underlying market structure or introduce synthetic distortions.
1. Trade Shuffling (Permutation without replacement)
Trade shuffling preserves the historical trade pool while randomly permuting chronological order across N simulations:
- Mechanics: Given an array of M closed trade returns
[r_1, r_2, ..., r_M], each iteration generates a random permutation of indices without replacement. - Preserved Properties: Total arithmetic return, win rate, profit factor, and empirical return distribution remain identical to the original backtest.
- Disrupted Properties: Chronological order and autocorrelation between consecutive trades.
- Diagnostic Objective: Isolates pure sequence risk. Shuffling answers: If the market had delivered these exact trades in an adverse sequence, how deep would the drawdown have reached?
2. Bootstrap Resampling (Sampling with replacement)
Bootstrap resampling draws M trades uniformly at random with replacement from the empirical distribution:
- Mechanics: Each trade in a simulated path is sampled independently from the trade log. Specific trades can appear multiple times, while others are omitted.
- Preserved Properties: Expected return and variance of the underlying trade distribution.
- Disrupted Properties: Total terminal return, trade composition, and serial correlation.
- Diagnostic Objective: Evaluates sample sensitivity and outlier fragility. It answers: Did strategy performance rely on a few windfall trades? How vulnerable is the portfolio if realized win rates dip by 4%?
3. Block Bootstrap (Preserving serial correlation)
Standard bootstrap assumes trade returns are independent and identically distributed (i.i.d.). In practice, systematic strategies often exhibit regime persistence, volatility clustering, and correlated losing streaks.
- Mechanics: Resamples contiguous blocks of trades of length k (e.g., k = 5 or 10 consecutive trades) with replacement.
- Preserved Properties: Short-term serial correlation, streakiness, and regime clustering within each block window.
- Disrupted Properties: Long-term global sequence across block transitions.
- Diagnostic Objective: Evaluates regime clustering risk. It answers: How does the portfolio survive when losing trades cluster during adverse market regimes?
Resampling Methodologies Comparison
| Resampling Method | Replacement? | Preserves Total Return? | Preserves Autocorrelation? | Primary Diagnostic Focus |
|---|---|---|---|---|
| Trade Shuffling | No | Yes (arithmetic PnL) | No | Pure sequence risk and path-dependent drawdown |
| Standard Bootstrap | Yes | No | No | Parameter sensitivity and outlier trade fragility |
| Block Bootstrap | Yes (block size k) | No | Yes (within window k) | Regime clustering and auto-correlated losing streaks |
Step-by-step Python implementation
Here is a vectorized Python implementation using NumPy and pandas. It simulates 1,000 equity paths from closed trade returns, tracks peak-to-trough drawdowns, and computes confidence intervals and ruin probability.
"""Monte Carlo Stress-Testing for Historical Trade Logs.

Vectorized simulation of path dependency, drawdown distributions,
and operational ruin probability using NumPy and pandas.
"""

from __future__ import annotations

from dataclasses import dataclass
import numpy as np
import pandas as pd


@dataclass(frozen=True)
class MonteCarloReport:
    """Statistical summary of Monte Carlo equity path simulation."""

    sample_trades: int
    num_simulations: int
    initial_capital: float
    median_terminal_equity: float
    percentile_5_terminal_equity: float
    percentile_95_terminal_equity: float
    median_max_drawdown: float
    percentile_90_max_drawdown: float
    percentile_95_max_drawdown: float
    percentile_99_max_drawdown: float
    ruin_probability: float

    def summary(self) -> str:
        """Format metrics into a clean text report."""
        return (
            "=====================================================\n"
            "             MONTE CARLO STRESS TEST REPORT          \n"
            "=====================================================\n"
            f"Trades Sampled        : {self.sample_trades}\n"
            f"Simulated Paths       : {self.num_simulations:,}\n"
            f"Initial Capital       : ${self.initial_capital:,.2f}\n"
            "-----------------------------------------------------\n"
            "TERMINAL EQUITY DISTRIBUTION:\n"
            f"  5th Percentile      : ${self.percentile_5_terminal_equity:,.2f}\n"
            f"  50th Percentile     : ${self.median_terminal_equity:,.2f}\n"
            f"  95th Percentile     : ${self.percentile_95_terminal_equity:,.2f}\n"
            "-----------------------------------------------------\n"
            "MAXIMUM DRAWDOWN DISTRIBUTION:\n"
            f"  50th Percentile     : {self.median_max_drawdown:.2%}\n"
            f"  90th Percentile     : {self.percentile_90_max_drawdown:.2%}\n"
            f"  95th Percentile     : {self.percentile_95_max_drawdown:.2%}\n"
            f"  99th Percentile     : {self.percentile_99_max_drawdown:.2%}\n"
            "-----------------------------------------------------\n"
            f"Ruin Probability (DD >= threshold) : {self.ruin_probability:.2%}\n"
            "====================================================="
        )


def run_monte_carlo(
    trade_returns: pd.Series | np.ndarray,
    num_simulations: int = 1_000,
    initial_capital: float = 10_000.0,
    ruin_drawdown_threshold: float = 0.25,
    mode: str = "bootstrap",
    random_seed: int = 42,
) -> tuple[MonteCarloReport, pd.DataFrame]:
    """Execute a vectorized Monte Carlo simulation over closed trade returns.

    Parameters
    ----------
    trade_returns : pd.Series | np.ndarray
        Array or Series of percentage returns per closed trade (e.g. +0.02 for +2%).
    num_simulations : int
        Total number of counterfactual equity paths to generate.
    initial_capital : float
        Starting account balance in portfolio base currency.
    ruin_drawdown_threshold : float
        Maximum drawdown fraction considered operational ruin (e.g. 0.25 for 25%).
    mode : str
        Resampling algorithm: 'bootstrap' (with replacement) or 'shuffle' (without).
    random_seed : int
        Seed for PRNG reproducibility.

    Returns
    -------
    report : MonteCarloReport
        Dataclass containing aggregated distribution statistics.
    paths_df : pd.DataFrame
        DataFrame of shape (num_trades + 1, num_simulations) containing all paths.
    """
    rng = np.random.default_rng(random_seed)
    returns_arr = np.asarray(trade_returns, dtype=np.float64)
    num_trades = len(returns_arr)

    if num_trades < 10:
        raise ValueError("Insufficient trade sample. Provide at least 10 closed trades.")

    # 1. Resample trade returns across all simulations simultaneously
    if mode == "bootstrap":
        idx_matrix = rng.integers(0, num_trades, size=(num_simulations, num_trades))
        sim_returns = returns_arr[idx_matrix]
    elif mode == "shuffle":
        sim_returns = np.empty((num_simulations, num_trades), dtype=np.float64)
        for i in range(num_simulations):
            sim_returns[i] = rng.permutation(returns_arr)
    else:
        raise ValueError(f"Invalid mode '{mode}'. Choose 'bootstrap' or 'shuffle'.")

    # 2. Compute compounded equity paths: E_t = E_0 * prod(1 + r_t)
    equity_multipliers = np.cumprod(1.0 + sim_returns, axis=1)
    initial_col = np.ones((num_simulations, 1), dtype=np.float64)
    equity_paths = np.hstack([initial_col, equity_multipliers]) * initial_capital

    # 3. Vectorized peak-to-trough drawdown calculation
    cumulative_peaks = np.maximum.accumulate(equity_paths, axis=1)
    drawdowns = (cumulative_peaks - equity_paths) / cumulative_peaks
    max_drawdowns_per_path = np.max(drawdowns, axis=1)

    # 4. Extract terminal equity and calculate risk metrics
    terminal_equity = equity_paths[:, -1]
    ruin_paths_count = np.count_nonzero(max_drawdowns_per_path >= ruin_drawdown_threshold)
    ruin_probability = float(ruin_paths_count / num_simulations)

    report = MonteCarloReport(
        sample_trades=num_trades,
        num_simulations=num_simulations,
        initial_capital=initial_capital,
        median_terminal_equity=float(np.median(terminal_equity)),
        percentile_5_terminal_equity=float(np.percentile(terminal_equity, 5)),
        percentile_95_terminal_equity=float(np.percentile(terminal_equity, 95)),
        median_max_drawdown=float(np.median(max_drawdowns_per_path)),
        percentile_90_max_drawdown=float(np.percentile(max_drawdowns_per_path, 90)),
        percentile_95_max_drawdown=float(np.percentile(max_drawdowns_per_path, 95)),
        percentile_99_max_drawdown=float(np.percentile(max_drawdowns_per_path, 99)),
        ruin_probability=ruin_probability,
    )

    paths_df = pd.DataFrame(equity_paths.T)
    return report, paths_df


if __name__ == "__main__":
    # Example: Synthesizing a realistic 150-trade sample
    # 53% win rate, average win +2.8%, average loss -2.2%
    np.random.seed(101)
    n_sample = 150
    wins = np.random.normal(0.028, 0.012, size=80)
    losses = np.random.normal(-0.022, 0.009, size=70)
    sample_pnl = np.concatenate([wins, losses])
    np.random.shuffle(sample_pnl)

    # Run Monte Carlo stress test with 1,000 bootstrap simulations
    report, _ = run_monte_carlo(
        trade_returns=sample_pnl,
        num_simulations=1_000,
        initial_capital=10_000.0,
        ruin_drawdown_threshold=0.25,
        mode="bootstrap",
        random_seed=42,
    )

    print(report.summary())
Interpreting the output: Ruin probability and drawdown distribution
When evaluating Monte Carlo results, single-point metrics like historical Sharpe ratio take a back seat to distribution percentiles and tail metrics.
1. The Drawdown Inflation Factor
In a historical backtest of 150–300 trades, the observed maximum drawdown is merely the worst drop that happened to materialize in that particular sequence.
Across 1,000 simulated paths, the 95th percentile maximum drawdown is typically 1.5x to 2.5x larger than the historical backtest figure. If a backtest showed a 12% peak drawdown, but the 95th percentile path experiences 26%, your risk budget must be calibrated for 26%. Sizing positions on the 12% figure risks severe undercapitalization when trade order scrambles in production.
2. Percentile Cones (Equity Fan Charts)
Plotting the percentile cone—spanning the 5th percentile (bearish envelope), 50th percentile (median path), and 95th percentile (bullish envelope)—reveals structural variance:
- Narrow, upward cones indicate consistent edge and low path sensitivity.
- Widely flaring cones, where the lower 5th percentile breaches initial capital, indicate high skewness. Even if median equity triples, the strategy carries a non-trivial risk of lingering in drawdown for months.
3. Operational Ruin vs. Theoretical Gambler's Ruin
In classical probability theory, ruin means total account liquidation ($0.00 balance). In professional trading, this metric is unhelpful.
Operational ruin is the drawdown threshold where:
- A prop firm or risk desk revokes account access (commonly an 8% to 10% trailing limit).
- External allocators mandate capital withdrawals (frequently at 15% to 20% drawdown).
- The trader suffers psychological fatigue and manually disables the strategy at the market trough.
If the simulation shows a 14% probability of breaching a 25% drawdown threshold, position sizing must be scaled down until operational ruin probability falls below tolerance (typically under 1%).
4. Underwater Duration and Recovery Horizon
Drawdown risk is two-dimensional: depth and duration. Monte Carlo paths frequently reveal that while a historical backtest recovered in 6 weeks, permuted sequences can extend recovery horizons beyond 6 months. Quant desks must confirm that investors and trading teams can endure these extended underwater horizons.
Assumptions, pitfalls, and when Monte Carlo fails
While Monte Carlo analysis is an essential stress-testing tool, its conclusions depend strictly on mathematical assumptions that can fail in live markets.
The i.i.d. Fallacy
Standard bootstrap and shuffling assume trades are independent and identically distributed. Systematic strategies frequently violate this assumption:
- Autocorrelation: Trend strategies produce winning streaks during macro trends and losing clusters during choppy consolidations.
- Volatility Regimes: Market shocks produce outsized return clusters followed by compressed volatility.
- Crisis Correlation: Uncorrelated assets often converge toward a correlation of 1.0 during liquidity shocks.
When return dependence is strong, standard shuffling underestimates drawdown depth. A Block Bootstrap must be used to preserve local correlation structure.
Garbage In, Garbage Out (GIGO)
Monte Carlo cannot repair a flawed backtest. If historical trades were generated with lookahead bias, unmodeled commission structures, or unrealistic fill assumptions on limit orders, resampling those trades simply generates thousands of counterfactual paths of flawed data. Resampling tests path dependency, not backtest integrity.
Position Sizing Feedback Loops
If a strategy uses dynamic volatility sizing, ATR-based stops, or fractional Kelly allocation, trade size depends directly on instantaneous portfolio equity at order time.
Post-hoc resampling of fixed returns breaks this dynamic feedback loop. If trade #10 was sized on a 20,000 balance, placing it after a 30% drawdown where capital was10,000 creates a dimensional distortion. For dynamic systems, walk-forward simulations should supplement trade-log resampling.
How OpenBacktesting Supports Post-Hoc Audits
This is where backtesting architecture matters. OpenBacktesting (version 0.2.1) is designed for deterministic, single-asset bar-by-bar backtesting:
- Models realistic order execution mechanics (market, limit, stop, stop-limit, trailing stop, OCO).
- Enforces user-configured commission schedules and slippage models, avoiding idealized midpoint fills.
- Exports structured, immutable trade logs (
trades_df) and Portfolio reports, with SQLite trial persistence for optimization runs.
Rather than embedding opaque stochastic modules inside the core engine, OpenBacktesting provides the clean, reproducible trade history needed to perform independent Monte Carlo audits in Python.
Summary checklist for robust stress-testing
Before allocating capital to any backtested strategy, complete this quantitative audit checklist:
- Verify Execution Friction: Confirm trades were executed with realistic commission schedules and conservative slippage models.
- Export Clean Trade Logs: Extract the unadulterated sequence of closed trade returns from your backtesting engine (e.g., OpenBacktesting's immutable Portfolio export).
- Run 1,000+ Trade Shuffles: Permute trade sequences without replacement to quantify path-dependent drawdown inflation.
- Run Bootstrap Resampling: Sample with replacement to evaluate sensitivity to outlier wins and sample variance.
- Apply Block Bootstrapping: If trades show serial correlation or regime clustering, use block sampling to preserve streak dynamics.
- Calibrate to 95th Percentile Drawdown: Size positions based on the 95th percentile simulated drawdown, not the nominal backtest figure.
- Audit Operational Ruin: Verify that the probability of crossing your operational drawdown limit (e.g., 20% or 25%) remains below 1%.
- Evaluate Recovery Durations: Confirm that the 90th percentile underwater duration aligns with your capital and psychological horizon.
For further exploration of reproducible strategy evaluation, read our guide on inspectable strategy research or consult the OpenBacktesting Documentation.