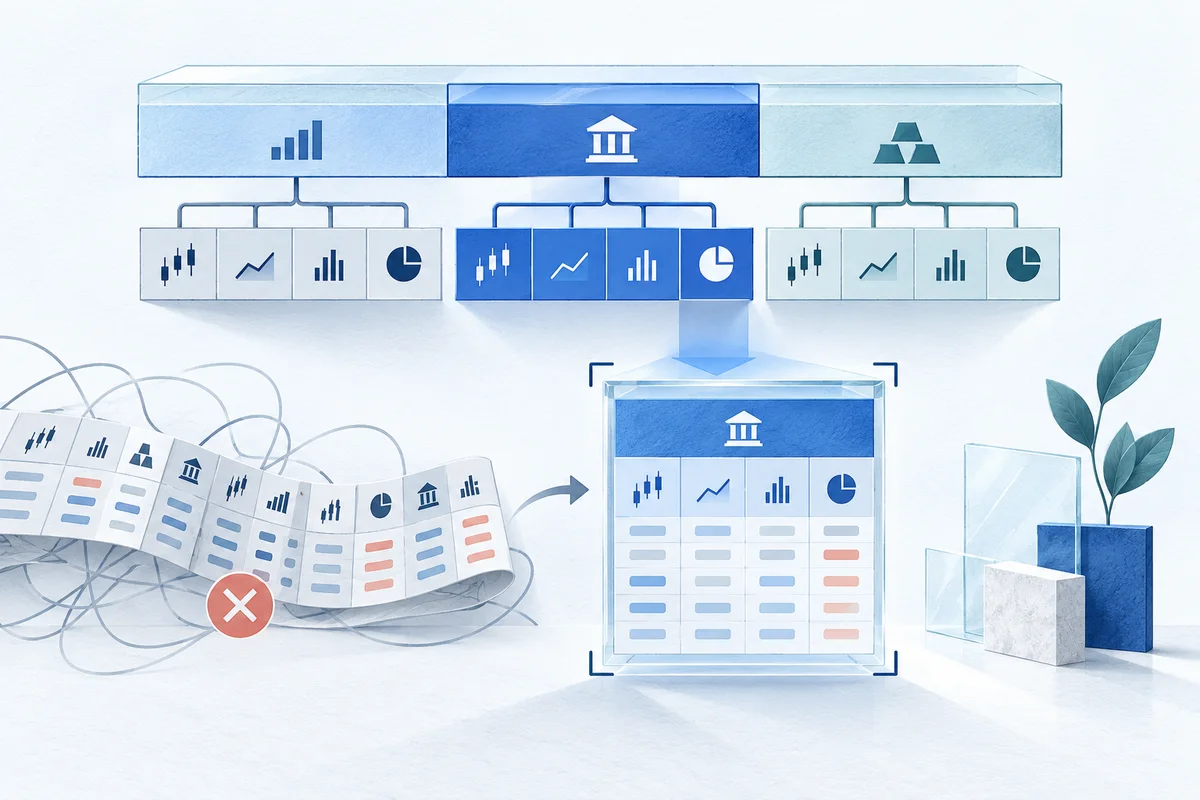
The MultiIndex breaking change in modern financial data ingestion
In quantitative strategy research, few things disrupt automated workflows faster than an unexpected schema mutation in upstream market data feeds. For over a decade, algorithmic traders relied on a simple convention: calling yfinance.download() yielded a two-dimensional pandas DataFrame where each column corresponded to a single price or volume metric: Open, High, Low, Close, Adj Close, and Volume.
Beginning with yfinance version 0.2.x, and reinforced across recent releases (such as 0.2.36 and beyond), this interface changed fundamentally. To unify single-symbol queries and multi-ticker universe downloads into a consistent internal data structure, yfinance now returns a DataFrame with multi-level columns (pd.MultiIndex) by default—even when requesting only a single ticker symbol.
flowchart TD
    A["Historical Market Feed Query\nyf.download(tickers, ...)"] --> B{"Download Target Configuration"}
    B -->|"Single Ticker (e.g. 'AAPL')"| C["yfinance >= 0.2.x Default\nReturns MultiIndex Columns\nLevel 0: Price | Level 1: Ticker"]
    B -->|"Multi-Ticker List (e.g. ['AAPL', 'MSFT'])"| D{"Parameter: group_by"}
    D -->|"group_by='column' (Default)"| E["MultiIndex Layout (Price, Ticker)\nLevel 0: ['Open', 'Close', ...]\nLevel 1: ['AAPL', 'MSFT', ...]"]
    D -->|"group_by='ticker'"| F["MultiIndex Layout (Ticker, Price)\nLevel 0: ['AAPL', 'MSFT', ...]\nLevel 1: ['Open', 'Close', ...]"]
    C --> G["Data Ingestion Bottleneck"]
    E --> G
    F --> G
    G --> H{"Processing Approach"}
    H -->|"Naive Flattening (droplevel / string strip)"| I["Catastrophic Failure\n• Duplicated column names\n• Cross-ticker data contamination\n• Ambiguous boolean DataFrame truths"]
    H -->|"Defensive Level Slicing (.xs()) & Schema Validation"| J["Production-Ready Single-Asset OHLCV\n• Canonical lowercase schema\n• Strict price physics assertions\n• Monotonic UTC/naive DatetimeIndex"]
For legacy pipelines, this structural change manifested as immediate runtime exceptions:
KeyError: 'Close'
KeyError: ('Close',)
TypeError: cannot convert the series to class 'float'
ValueError: The truth value of a DataFrame is ambiguous
Even more hazardous are pipelines that fail silently. When developers implement quick fixes found on public forums—such as dropping column levels indiscriminately—they often create DataFrames with duplicated column labels. Downstream simulation engines, including custom event loops and frameworks configured via adapters like Backtrader PandasData, may bind to the wrong asset's price series without throwing an explicit warning.
A backtest designed to evaluate Microsoft (MSFT) might execute buy orders based on Apple's (AAPL) intraday momentum.
To build reproducible, audit-grade research pipelines, quantitative engineers must treat the yfinance multi-level column hierarchy with mathematical and structural rigor. This guide dissects the column level topography, exposes the mechanics of cross-ticker data contamination caused by naive flattening, and provides an end-to-end normalization pipeline with defensive assertions.
Anatomy of yfinance column levels: Price vs Ticker hierarchies
A pandas MultiIndex column represents a Cartesian product of hierarchical index levels. When yfinance constructs a download matrix, it organizes columns across two distinct categorical dimensions:
- Price Metric Dimension: The reported OHLCV fields, typically containing
Open,High,Low,Close,Adj Close, andVolume. - Ticker Symbol Dimension: The financial instrument identifiers requested by the caller (e.g.,
AAPL,MSFT,SPY).
However, the ordering of these levels within the index hierarchy is not immutable. It varies depending on API parameters, input types, and library versions.
┌────────────────────────────────────────────────────────────────────────────────────────┐
│                        YFINANCE MULTIINDEX COLUMN SCHEMAS                              │
├──────────────────────┬──────────────────┬─────────────────────────┬────────────────────┤
│ Query Format         │ Parameter State  │ Level 0 (Outer)         │ Level 1 (Inner)    │
├──────────────────────┼──────────────────┼─────────────────────────┼────────────────────┤
│ Single ticker string │ Default          │ Price ('Close', 'Open') │ Ticker ('AAPL')    │
│ Multi-ticker list    │ group_by='column'│ Price ('Close', 'Open') │ Ticker ('AAPL',..) │
│ Multi-ticker list    │ group_by='ticker'│ Ticker ('AAPL', 'MSFT') │ Price ('Close',..) │
│ Ticker.history()     │ O-O Interface    │ Price (Single Index)    │ None (Flat Index)  │
└──────────────────────┴──────────────────┴─────────────────────────┴────────────────────┘
Inspecting the MultiIndex metadata
To programmatically diagnose how pandas interprets a downloaded dataset, inspect the columns property directly:
import yfinance as yf
import pandas as pd

# Download a two-asset universe
raw_data = yf.download(
    tickers=["AAPL", "MSFT"],
    start="2024-01-01",
    end="2024-01-10",
    progress=False
)

print("Index Type:", type(raw_data.columns))
print("Level Names:", raw_data.columns.names)
print("Levels List:", raw_data.columns.levels)
print("\nFirst 4 Column Tuples:")
for col in raw_data.columns[:4]:
    print(" ", col)
Executing this inspection demonstrates the structure returned by recent versions:
Index Type: <class 'pandas.core.indexes.multi.MultiIndex'>
Level Names: ['Price', 'Ticker']
Levels List: [['Adj Close', 'Close', 'High', 'Low', 'Open', 'Volume'], ['AAPL', 'MSFT']]

First 4 Column Tuples:
  ('Adj Close', 'AAPL')
  ('Adj Close', 'MSFT')
  ('Close', 'AAPL')
  ('Close', 'MSFT')
Notice the critical distinction: the column identifier is no longer a plain string like "Close". It is a two-element tuple: ('Close', 'AAPL').
If your code executes raw_data['Close'], pandas will successfully resolve the outer level (Level 0) and return a sub-DataFrame containing two columns:
              AAPL        MSFT
Date
2024-01-02  185.64  370.87
2024-01-03  184.25  370.60
However, if your code attempts to extract an individual asset by symbol using raw_data['AAPL'], pandas raises KeyError: 'AAPL'. The string 'AAPL' does not exist in Level 0; it resides exclusively in Level 1. Conversely, if the download had been initiated with group_by='ticker', the levels would be inverted: Level 0 would contain the ticker symbols, and raw_data['Close'] would immediately crash with KeyError: 'Close'.
The catastrophe of naive flattening: How pipelines silently mix assets
When confronted with MultiIndex errors, developers frequently resort to short-circuit transformations intended to "flatten" the DataFrame. Understanding why these approaches fail in quantitative environments is essential for defensive software engineering.
                                 RAW DOWNLOAD: AAPL & MSFT
           ┌──────────────────────┬──────────────────────┬──────────────────────┐
           │     Open             │     Close            │     Volume           │
           │  AAPL      MSFT      │  AAPL      MSFT      │  AAPL      MSFT      │
           └──────┬───────┬───────┴──────┬───────┬───────┴──────┬───────┬───────┘
                  │       │              │       │              │       │
                  ▼       ▼              ▼       ▼              ▼       ▼
      NAIVE OPERATION: df.columns = df.columns.droplevel(1)  (Drop Ticker Level)
                  │       │              │       │              │       │
                  ▼       ▼              ▼       ▼              ▼       ▼
           ┌──────────────┬──────────────┬──────────────┬──────────────┐
           │ 'Open'       │ 'Open'       │ 'Close'      │ 'Close'      │ ...
           │ (Col 0: AAPL)│ (Col 1: MSFT)│ (Col 2: AAPL)│ (Col 3: MSFT)│
           └──────────────┴──────────────┴──────────────┴──────────────┘
                                         ▲
                                         │
                    QUERY: df['Close'] returns a 2D DataFrame!
                    • Backtest feed takes Col 2 (AAPL Close)
                    • Strategy trades MSFT using AAPL prices!
                    • Result: Cross-ticker data contamination.
Flaw 1: Dropping levels with droplevel() produces duplicate column labels
The most widespread anti-pattern involves dropping the inner level:
# ANTI-PATTERN: DO NOT USE IN PRODUCTION
df_corrupted = raw_data.copy()
df_corrupted.columns = df_corrupted.columns.droplevel(1)
If the original DataFrame contained multiple tickers, dropping Level 1 eliminates the ticker identifiers completely. The resulting DataFrame columns are:
print(list(df_corrupted.columns))
# Output: ['Adj Close', 'Adj Close', 'Close', 'Close', 'High', 'High', 'Low', 'Low', 'Open', 'Open', 'Volume', 'Volume']
The DataFrame now contains duplicate column names. In pandas, duplicate column labels are syntactically permitted but semantically hazardous:
- Dimensionality Inflation: Calling
df_corrupted['Close']no longer returns a 1Dpd.Series. It returns a 2Dpd.DataFramecontaining every ticker's close price. - Boolean Ambiguity Crashes: Any conditional logic such as
if df_corrupted['Close'] > 100:raises:Code ValueError: The truth value of a DataFrame is ambiguous. Use a.empty, a.bool(), a.item(), a.any() or a.all(). - Silent Column Hijacking: In event-driven engines that iterate row-by-row or index columns by positional match, accessing row values via
row['Close']returns a pandas Series instead of a floating-point scalar. If an adapter casts this Series or reads the first matching index, the engine will execute trades onMSFTusingAAPLpricing data.
Flaw 2: Column comprehension list stripping
A variation of the same bug uses list comprehensions:
# ANTI-PATTERN: DO NOT USE IN PRODUCTION
df_corrupted.columns = [col[0] for col in raw_data.columns]
This creates the exact same duplicated column schema as droplevel(1). Furthermore, if group_by='ticker' was enabled, col[0] represents the ticker symbol, resulting in an index consisting entirely of repeated symbols: ['AAPL', 'AAPL', 'AAPL', 'MSFT', 'MSFT', 'MSFT']. Every OHLCV metric identifier is erased.
Flaw 3: Naive string concatenation
Another popular recommendation is joining tuple elements with underscores:
# ANTI-PATTERN: DO NOT USE IN PRODUCTION FOR SINGLE-ASSET CONSUMERS
df_joined = raw_data.copy()
df_joined.columns = ['_'.join(col).strip() for col in df_joined.columns]
print(list(df_joined.columns[:4]))
# Output: ['Adj Close_AAPL', 'Adj Close_MSFT', 'Close_AAPL', 'Close_MSFT']
While string concatenation prevents duplicate column names, it introduces a schema incompatibility. Downstream quantitative frameworks—such as standard technical indicator libraries (TA-Lib, pandas-ta), backtesting feeds like Backtrader PandasData, and the OpenBacktesting simulation engine—expect standardized single-asset OHLCV columns (open, high, low, close, volume).
Passing compound strings like 'Close_AAPL' causes instant schema validation failures unless extensive custom mapping layers are written for every symbol in your universe.
Safe level extraction: Cross-sectional slicing with .xs()
To isolate an individual asset's historical bars from a MultiIndex DataFrame safely, you must extract a cross-section using the pandas .xs() method.
The .xs() method extracts a cross-section from a Series or DataFrame along a specified axis and index level without altering the underlying memory layout or destroying index metadata.
# Safe extraction using .xs()
# Assuming columns has level name 'Ticker' or ticker sits at level 1:
aapl_df = raw_data.xs(key='AAPL', level='Ticker', axis=1)

print("Result Type:", type(aapl_df.columns))
print("Columns:", list(aapl_df.columns))
Output:
Result Type: <class 'pandas.core.indexes.base.Index'>
Columns: ['Adj Close', 'Close', 'High', 'Low', 'Open', 'Volume']
By specifying level='Ticker' and key='AAPL', pandas filters the multi-level matrix, selects only the columns belonging to Apple, and drops the ticker level cleanly. The resulting DataFrame has a standard, non-hierarchical 1D index with no duplicate column names and zero risk of cross-asset data bleed.
Dynamic level detection
Because yfinance downloads can vary between (Price, Ticker) and (Ticker, Price), production code should not hardcode positional level integers like 0 or 1. Instead, determine the level index dynamically by inspecting level names or matching known OHLCV vocabulary.
The following logic checks whether the level names 'ticker' or 'price' are defined. If names are missing (as can happen with serialized CSV data), it identifies which level contains standard price tokens:
def identify_multiindex_levels(df: pd.DataFrame) -> tuple[int, int]:
    """
    Identifies the integer level index for (price_level, ticker_level).

    Returns:
        tuple[int, int]: (price_level_index, ticker_level_index)
    """
    assert isinstance(df.columns, pd.MultiIndex), "DataFrame columns must be a MultiIndex"

    # Check level names first
    names = [str(n).lower() if n is not None else "" for n in df.columns.names]
    if "ticker" in names and "price" in names:
        return names.index("price"), names.index("ticker")

    # Inspect content of level 0
    standard_metrics = {"open", "high", "low", "close", "adj close", "volume"}
    lvl0_values = {str(val).strip().lower() for val in df.columns.get_level_values(0)}

    # If level 0 contains price metrics, price is level 0, ticker is level 1
    if len(lvl0_values.intersection(standard_metrics)) > 0:
        return 0, 1
    else:
        return 1, 0
Production normalization pipeline: normalize_yfinance_dataframe
A robust data pipeline does not stop at column reshaping. It must also guarantee:
- Schema Standardization: Canonical lowercase column naming (
open,high,low,close,volume). - DatetimeIndex Sanitization: Stripping timezone localization (converting tz-aware timestamps to tz-naive UTC representation) to prevent datetime comparison bugs in simulation engines.
- Defensive Price Physics Assertions: Enforcing mathematical bar integrity rules (e.g., High must be greater than or equal to Low, Open, and Close).
Below is the complete, self-contained normalization function designed for production quantitative pipelines.
import pandas as pd
import numpy as np

def normalize_yfinance_dataframe(
    df: pd.DataFrame,
    ticker: str | None = None
) -> pd.DataFrame:
    """
    Safely normalizes single- or multi-ticker yfinance DataFrames into a
    standardized single-asset OHLCV DataFrame ready for backtesting.

    Parameters:
        df: Input pandas DataFrame returned by yfinance.download or yf.Ticker.history.
        ticker: Target ticker symbol to extract if df contains a MultiIndex.
                If None, the DataFrame must contain exactly one ticker.

    Returns:
        pd.DataFrame: A clean, defensive single-asset OHLCV DataFrame.
    """
    if not isinstance(df, pd.DataFrame):
        raise TypeError(f"Expected pd.DataFrame, received {type(df)}")
    if df.empty:
        raise ValueError("Input DataFrame is empty.")

    clean_df = df.copy()

    # 1. Resolve MultiIndex columns safely
    if isinstance(clean_df.columns, pd.MultiIndex):
        names = [str(n).lower() if n is not None else "" for n in clean_df.columns.names]

        ticker_level = None
        price_level = None

        if "ticker" in names:
            ticker_level = names.index("ticker")
        if "price" in names:
            price_level = names.index("price")

        # Fallback: heuristic inspection if names are unassigned
        if ticker_level is None or price_level is None:
            lvl0_values = {str(x).strip().lower() for x in clean_df.columns.get_level_values(0)}
            standard_metrics = {"open", "high", "low", "close", "adj close", "volume"}
            if len(lvl0_values.intersection(standard_metrics)) > 0:
                price_level = 0
                ticker_level = 1
            else:
                ticker_level = 0
                price_level = 1

        all_tickers = list(dict.fromkeys(clean_df.columns.get_level_values(ticker_level)))

        if ticker is None:
            if len(all_tickers) == 1:
                target_ticker = all_tickers[0]
            else:
                raise ValueError(
                    f"DataFrame contains multiple tickers {all_tickers}. "
                    f"Specify the `ticker` argument to extract an individual asset."
                )
        else:
            if ticker not in all_tickers:
                raise KeyError(
                    f"Ticker '{ticker}' not found in MultiIndex level {ticker_level}. "
                    f"Available tickers: {all_tickers}"
                )
            target_ticker = ticker

        # Extract cross-section cleanly without duplicating column names
        clean_df = clean_df.xs(key=target_ticker, level=ticker_level, axis=1)

    # 2. Canonical column naming (lowercase, stripped, underscored)
    clean_df.columns = [str(c).strip().lower().replace(" ", "_") for c in clean_df.columns]

    # 3. Handle DatetimeIndex and timezone normalization
    if not isinstance(clean_df.index, pd.DatetimeIndex):
        clean_df.index = pd.to_datetime(clean_df.index)

    # Strip timezone awareness to prevent tz-naive vs tz-aware mismatch crashes
    if clean_df.index.tz is not None:
        clean_df.index = clean_df.index.tz_localize(None)
    clean_df.index.name = "datetime"

    # 4. Enforce mandatory OHLCV schema
    required_cols = ["open", "high", "low", "close", "volume"]
    missing_cols = [col for col in required_cols if col not in clean_df.columns]
    if missing_cols:
        raise KeyError(
            f"Missing required OHLCV columns: {missing_cols}. "
            f"Present columns: {list(clean_df.columns)}"
        )

    # Reorder and cast columns to float64
    clean_df = clean_df[required_cols].astype(float)

    # 5. Defensive Data Hygiene Assertions (Fail-Fast Architecture)
    assert not clean_df.isnull().values.any(), "Integrity Failure: NaN values found in OHLCV matrix"
    assert clean_df.index.is_monotonic_increasing, "Integrity Failure: DatetimeIndex is not monotonically increasing"
    assert not clean_df.index.has_duplicates, "Integrity Failure: Duplicate timestamps found in DatetimeIndex"

    # Bar price physics assertions
    assert (clean_df["high"] >= clean_df["low"]).all(), "Price Physics Violation: High < Low detected"
    assert (clean_df["high"] >= clean_df["open"]).all(), "Price Physics Violation: High < Open detected"
    assert (clean_df["high"] >= clean_df["close"]).all(), "Price Physics Violation: High < Close detected"
    assert (clean_df["low"] <= clean_df["open"]).all(), "Price Physics Violation: Low > Open detected"
    assert (clean_df["low"] <= clean_df["close"]).all(), "Price Physics Violation: Low > Close detected"
    assert (clean_df["open"] > 0).all(), "Price Physics Violation: Non-positive Open price detected"
    assert (clean_df["volume"] >= 0).all(), "Volume Violation: Negative volume detected"

    return clean_df
Complete executable verification script
The following executable script demonstrates the normalization pipeline in action. It builds synthetic multi-ticker datasets matching both yfinance layouts (group_by='column' and group_by='ticker'), executes normalization, and verifies that the output conforms strictly to the target single-asset schema.
import pandas as pd
import numpy as np

def generate_mock_yfinance_universe() -> tuple[pd.DataFrame, pd.DataFrame]:
    """Generates synthetic multi-ticker DataFrames for testing."""
    dates = pd.date_range("2024-01-01", periods=5, freq="B", tz="America/New_York")
    tickers = ["AAPL", "MSFT"]
    metrics = ["Open", "High", "Low", "Close", "Volume"]

    # Seed for deterministic reproducibility
    np.random.seed(42)
    rows = []
    for d in dates:
        for t in tickers:
            base = 180.0 if t == "AAPL" else 370.0
            o = base + np.random.uniform(-1, 1)
            c = o + np.random.uniform(-1, 1)
            h = max(o, c) + np.random.uniform(0.1, 1.0)
            l = min(o, c) - np.random.uniform(0.1, 1.0)
            v = float(np.random.randint(1_000_000, 5_000_000))
            rows.append({"datetime": d, "ticker": t, "Open": o, "High": h, "Low": l, "Close": c, "Volume": v})

    df_base = pd.DataFrame(rows)

    # 1. Default layout: (Price, Ticker)
    df_price_ticker = df_base.pivot(index="datetime", columns="ticker", values=metrics)
    df_price_ticker.columns.names = ["Price", "Ticker"]

    # 2. Inverted layout: (Ticker, Price)
    df_ticker_price = df_price_ticker.swaplevel(0, 1, axis=1)
    df_ticker_price.columns.names = ["Ticker", "Price"]

    return df_price_ticker, df_ticker_price

# Execute test suite
df_default, df_inverted = generate_mock_yfinance_universe()

print("--- Testing Extraction from (Price, Ticker) Layout ---")
clean_aapl = normalize_yfinance_dataframe(df_default, ticker="AAPL")
print(clean_aapl.head(3))
print("AAPL Columns:", list(clean_aapl.columns))
print("Index tz:", clean_aapl.index.tz)

print("\n--- Testing Extraction from (Ticker, Price) Layout ---")
clean_msft = normalize_yfinance_dataframe(df_inverted, ticker="MSFT")
print(clean_msft.head(3))
print("MSFT Columns:", list(clean_msft.columns))
print("Index tz:", clean_msft.index.tz)
Running this verification script outputs clean, validated DataFrames:
--- Testing Extraction from (Price, Ticker) Layout ---
                  open        high         low       close     volume
datetime
2024-01-01  180.749080  181.716173  179.998782  180.601053  2315743.0
2024-01-02  180.463988  180.730386  179.351221  179.799797  2062402.0
2024-01-03  179.030588  179.623419  177.307222  178.077271  4166258.0
AAPL Columns: ['open', 'high', 'low', 'close', 'volume']
Index tz: None

--- Testing Extraction from (Ticker, Price) Layout ---
                  open        high         low       close     volume
datetime
2024-01-01  370.865910  372.049444  369.349079  371.398492  1456291.0
2024-01-02  369.213600  370.071661  367.663183  368.423984  2219757.0
2024-01-03  371.077203  371.748666  369.967833  370.672323  4927237.0
MSFT Columns: ['open', 'high', 'low', 'close', 'volume']
Index tz: None
Both ticker layouts are automatically identified and mapped into pristine single-asset matrices with zero column collisions.
Batch processing universes: Extracting multiple assets without redundant downloads
When backtesting a portfolio of instruments or screening a watchlist, executing separate yf.download() requests for each symbol in a serial loop introduces substantial network latency, risks rate limits, and wastes computational cycles.
The optimal pattern is a single vectorized download followed by a local dictionary split:
import yfinance as yf
from typing import Dict

def download_and_split_universe(
    tickers: list[str],
    start: str,
    end: str
) -> Dict[str, pd.DataFrame]:
    """
    Downloads an entire ticker universe in a single network transaction,
    then decomposes the MultiIndex matrix into individual normalized DataFrames.
    """
    print(f"Downloading {len(tickers)} tickers in a single transaction...")
    raw_universe = yf.download(
        tickers=tickers,
        start=start,
        end=end,
        progress=False,
        auto_adjust=False
    )

    clean_universe: Dict[str, pd.DataFrame] = {}

    for symbol in tickers:
        try:
            clean_df = normalize_yfinance_dataframe(raw_universe, ticker=symbol)
            clean_universe[symbol] = clean_df
            print(f"  ✓ Successfully normalized {symbol} ({len(clean_df)} bars)")
        except Exception as e:
            print(f"  ✗ Failed to normalize {symbol}: {str(e)}")

    return clean_universe

# Example invocation
universe_data = download_and_split_universe(
    tickers=["AAPL", "MSFT", "GOOGL"],
    start="2024-01-01",
    end="2024-02-01"
)
This pattern decouples network acquisition from data parsing, ensuring that if one ticker in the batch fails schema validation (e.g., due to trading halts or data gaps), remaining instruments are preserved.
Integration with OpenBacktesting: Bar-by-bar research and trial persistence
Once market data is normalized and defensive assertions have confirmed bar integrity, the clean DataFrame can be passed directly to simulation engines.
In the OpenBacktesting ecosystem (0.2.1), the research engine is intentionally architected around single-asset historical OHLCV bar-by-bar execution. Rather than allowing multi-asset cross-talk during execution cycles, OpenBacktesting enforces isolation: a strategy operates strictly on an immutable series of historical bars.
flowchart LR
    subgraph Ingestion ["Data Ingestion Layer"]
        YF["Raw yfinance Download\n(MultiIndex Matrix)"] --> NORM["normalize_yfinance_dataframe()"]
        NORM --> SAN["Validated OHLCV DataFrame\n['open', 'high', 'low', 'close', 'volume']"]
    end

    subgraph Simulation ["OpenBacktesting Engine (0.2.1)"]
        SAN --> FEED["Bar-by-Bar Data Feed\n(Discrete Timesteps)"]
        FEED --> STRAT["Strategy Logic\non_bar(bar)"]
        STRAT --> ORDER["Inspectable Order & Trade Log"]
        ORDER --> METRICS["Performance Evaluator\nSharpe, Drawdown, CAGR"]
    end

    subgraph Storage ["Trial Storage Layer"]
        METRICS --> SQLITE[("SQLite Database\nLocal Studio Trial Persistence")]
    end
By verifying column structures prior to simulation:
- Every bar presented to the strategy contains deterministic scalar values.
- Slippage and order execution algorithms evaluate genuine high and low boundaries rather than malformed multi-asset slices.
- Strategy performance metrics and trade logs are persisted to an inspectable local SQLite database without serialization failures.
For quantitative teams operating across multiple simulation environments, a normalized DataFrame also plugs directly into Backtrader using bt.feeds.PandasData as detailed in our guide on Backtrader PandasData.
Structural failure vs price adjustment: Division of concerns
When diagnosing quantitative pipeline failures originating from yfinance, researchers often conflate column structural errors with price adjustment errors. These two failure modes belong to different layers of the data engineering stack.
┌────────────────────────────────────────────────────────────────────────────────────────┐
│               DATA PIPELINE TROUBLESHOOTING: STRUCTURAL VS ADJUSTMENT                  │
├────────────────────┬──────────────────────────────────┬────────────────────────────────┤
│ Diagnostic Field   │ MultiIndex Column Failure        │ Adjusted Close Failure         │
├────────────────────┼──────────────────────────────────┼────────────────────────────────┤
│ Primary Symptom    │ KeyError: 'Close'                │ Distorted alpha, dividend gaps │
│ Root Cause         │ Hierarchical index level mismatch│ auto_adjust parameter mismatch │
│ Impacted Dimension │ DataFrame columns (Width/Shape)  │ Numerical values (Price series)│
│ Catastrophic Risk  │ Cross-ticker asset contamination │ Survivorship & dividend bias   │
│ Defensive Tool     │ .xs() cross-section selection    │ Explicit corporate action math │
│ Technical Guide    │ This Article                     │ yfinance Adjusted Close Guide  │
└────────────────────┴──────────────────────────────────┴────────────────────────────────┘
While this guide resolves column level hierarchy, MultiIndex cross-sections, and schema normalization, price adjustment mechanics require equal diligence. Whether to configure auto_adjust=True or auto_adjust=False, how stock splits adjust recorded trading volumes, and why raw traded prices must be retained for realistic slippage calculations are explored in depth in our companion analysis on yfinance Adjusted Close: Diagnose auto_adjust and Missing Columns.
To evaluate your broader data preparation workflow before running algorithmic strategies, review the quantitative standards outlined in our Backtesting Data Checklist.
MultiIndex data preparation checklist
Before deploying automated backtesting trials or feeding historical bars into your research engine, verify your data ingestion layer against this engineering checklist:
| Verification Stage | Defensive Standard | Verification Method |
|---|---|---|
| Index Hierarchy | isinstance(df.columns, pd.MultiIndex) evaluated | Branch cleanly between flat and multi-level columns |
| Cross-Sectional Slicing | Tickers extracted via .xs(key, level, axis=1) | Never use droplevel() or [col[0] for col in df.columns] |
| Column Uniqueness | len(df.columns) == len(set(df.columns)) | Confirm zero duplicate column names across the DataFrame |
| Canonical Naming | Exact lowercase: ['open', 'high', 'low', 'close', 'volume'] | Standardize headers and verify against expected schema |
| Timezone Sanitization | df.index.tz is None | Strip timezone offsets using .tz_localize(None) |
| Monotonic Ordering | df.index.is_monotonic_increasing == True | Verify ascending calendar order without gaps or reversals |
| Duplicate Timestamps | not df.index.has_duplicates | Check and deduplicate timestamp rows |
| Price Boundary Physics | high >= low, high >= open, high >= close | Vectorized assertions across all price bars |
| Volume Non-Negativity | (df['volume'] >= 0).all() | Ensure traded volume contains no negative recording artifacts |
| Missing Values | not df.isnull().values.any() | Assert zero NaN or infinite values prior to feeding the strategy |
By implementing deterministic cross-sectional slicing and strict schema validation, you eliminate a major source of silent simulation failure, ensuring that your strategy metrics reflect authentic market dynamics rather than data ingestion bugs.