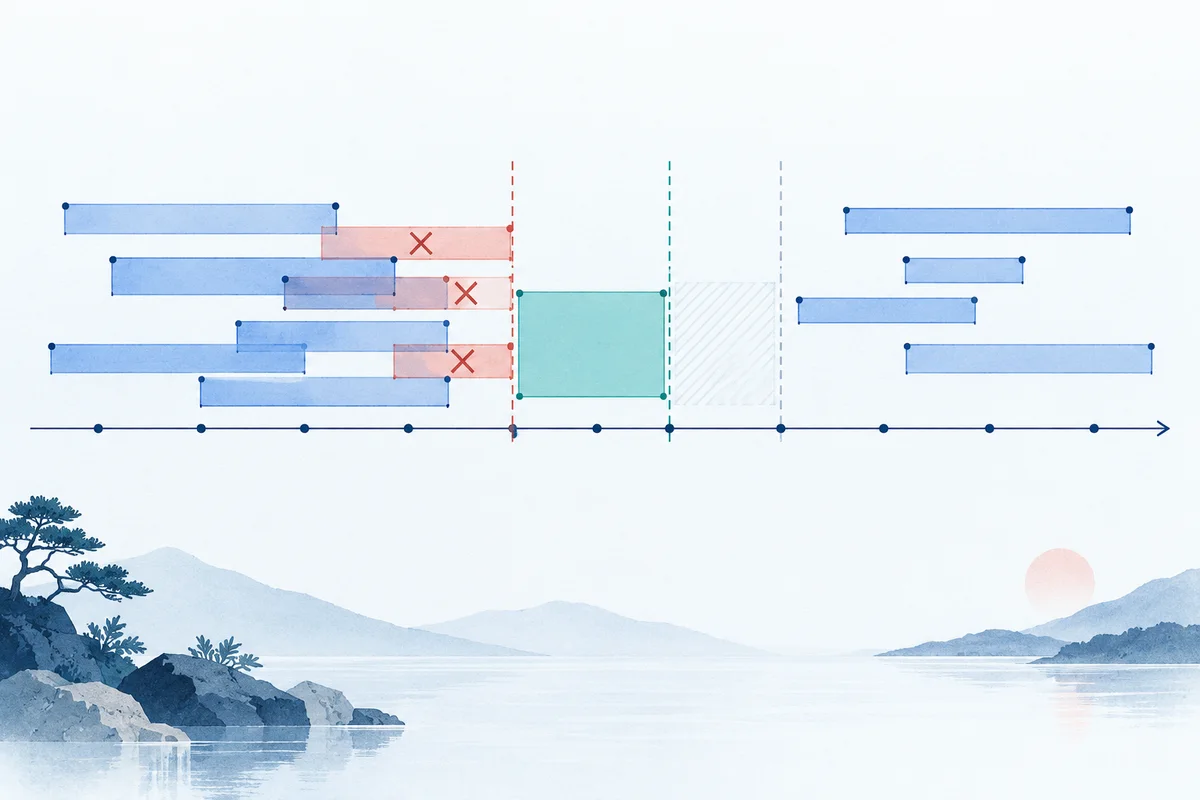
The Flaw in Standard Cross-Validation for Financial Time Series
In standard statistical machine learning, cross-validation relies on a foundational assumption: observations are independent and identically distributed (i.i.d.). Under the i.i.d. framework, shuffling rows in a feature matrix X and partitioning them into K uniform slices via scikit-learn's KFold yields unbiased estimates of out-of-sample generalization error.
In financial machine learning, that assumption is catastrophically false.
Financial market data is governed by the arrow of time, strong serial autocorrelation, and non-stationary regime shifts. When researchers apply naive cross-validation splitters to financial time series, the resulting test metrics are wildly over-optimistic. The model does not discover authentic alpha; it simply exploits subtle temporal bridges between training and testing folds.
As detailed in our foundational guide on backtesting machine learning models, data leakage is the primary reason why quantitative algorithms boasting 80% out-of-sample directional accuracy during research collapse into continuous drawdowns upon live capital allocation.
Standard K-Fold (Fatal Leakage in Finance):
Fold 1 Test: [   TEST   ] [  TRAIN  ] [  TRAIN  ] [  TRAIN  ] [  TRAIN  ]
Fold 3 Test: [  TRAIN  ] [  TRAIN  ] [   TEST   ] [  TRAIN  ] [  TRAIN  ]
                           ▲                    ▲
                           └─ Information leaks ┘
                              across boundaries!
While many practitioners recognize that random shuffling destroys temporal causality and switch to simple sequential walk-forward splits, standard chronological slicing still fails to solve the most pervasive leakage vector in algorithmic trading: overlapping financial labels.
Financial labels are not instantaneous point-in-time measurements. Whether using fixed multi-bar forward horizons or dynamic event-driven barrier methods, labels span holding periods from bar t to bar t + h. If any part of a training label's evaluation window intersects with a test fold, future price movements are injected directly into the training features.
To eliminate this contamination without discarding the statistical power of cross-validation, quantitative researchers must employ purged cross validation paired with sample embargoing.
Anatomy of an Overlapping Financial Label: Why Fixed Gaps Fail
To understand why simple time-series splits fail, we must examine how financial targets are constructed.
In tabular machine learning benchmarks, an observation at row i has features X_i and a simultaneous target y_i. In systematic trading, an observation at timestamp t_{i,0} represents the market state when a trade decision is evaluated. However, the outcome y_i is determined over an extended holding interval:
Sample Evaluation Window: [t_{i,0}, t_{i,1}]
where:
  t_{i,0} = Timestamp when prediction is made (features known)
  t_{i,1} = Timestamp when position is closed and label is realized
The Variable-Length Reality of the Triple Barrier Method
In modern quantitative research—most notably formalized by Marcos López de Prado—labels are rarely generated from fixed k-day returns. Fixed-time horizons ignore market volatility, forcing positions to close at arbitrary clock intervals regardless of market state.
Instead, robust pipelines deploy event-driven labeling such as the Triple Barrier Method. An active position terminates upon the occurrence of the earliest of three conditions:
- Upper horizontal barrier: Price hits a profit-taking threshold (
+kappa * sigma_t). - Lower horizontal barrier: Price hits a stop-loss threshold (
-kappa * sigma_t). - Vertical barrier: A maximum holding timeout is reached (
t_{i,0} + Hbars).
Because price path volatility varies wildly across regimes, the holding period Delta_t_i = t_{i,1} - t_{i,0} is dynamic and stochastic. One sample might exit after 2 bars due to an immediate volatility breakout, while another remains open for 15 bars until the vertical timeout expires.
Bar:       01  02  03  04  05  06  07  08  09  10  11  12  13  14  15
Sample A:  [=======] (exited at bar 04: take-profit hit)
Sample B:      [================================] (exited at bar 13: vertical barrier hit)
Sample C:                  [===] (exited at bar 08: stop-loss hit)
The Failure of Static Splitting Gaps
Practitioners often attempt to prevent boundary leakage by inserting a fixed gap (e.g., scikit-learn's TimeSeriesSplit(gap=5)) between the training and testing sets.
The flaw in this heuristic is immediate: a fixed gap cannot guarantee boundary isolation for variable-length labels.
Consider a test fold spanning bars 50 through 100:
- Suppose a fixed gap of 5 bars is enforced, training on bars 0 through 44.
- An entry signal is triggered at bar 42. Due to low market volatility, its triple-barrier position does not resolve until bar 54.
- The training label
y_{42}is computed using high, low, and close prices from bar 43 through bar 54. - Bars 50 through 54 belong entirely to the out-of-sample test fold.
Historical Timeline:
... | Bar 42 | Bar 43 | ... | Bar 49 | Bar 50 | Bar 51 | ... | Bar 54 | ...
    [--- Train Set ---]     [- Gap -] [---------- Test Set ----------]

Sample at Bar 42:
    Entry: Bar 42 (Train)
    Holding Span: ------------------------------------> Exit: Bar 54 (Test!)

Result: Training target y_42 incorporates price action from the Test Fold!
Because the training target incorporates price action from within the test period, the model learns spurious correlations that will never exist in live execution. When an algorithm fits parameters on labels containing future test-period price paths, out-of-sample backtest scores become completely meaningless.
To enforce mathematical rigor, boundary isolation must be calculated dynamically for every observation based on its explicit label termination timestamp t_{i,1}.
Purging vs. Embargoing: Two Distinct Isolation Mechanisms
To completely eliminate information leakage while preserving valid training samples, we must deploy two distinct, complementary operations: purging and embargoing.
flowchart LR
    subgraph Timeline["Chronological Partitions for a Central Test Fold"]
        direction LR
        TrainLeft["Training Set (Past)"]
        PurgeLeft["Purged Zone<br/>(Train labels overlap Test start)"]
        TestFold["Test Fold<br/>[T_start, T_end]"]
        PurgeRight["Purged Zone<br/>(Test labels overlap Train start)"]
        Embargo["Embargo Zone<br/>(Autoregressive feature memory)"]
        TrainRight["Training Set (Future)"]
    end
    TrainLeft --> PurgeLeft
    PurgeLeft --> TestFold
    TestFold --> PurgeRight
    PurgeRight --> Embargo
    Embargo --> TrainRight
1. Purging: Resolving Overlapping Label Spans
Purging eliminates any training observation whose label evaluation span intersects with the test evaluation span.
Formally, let the test fold span start time T_{test, start} and end time T_{test, end}. A training observation i with entry timestamp t_{i,0} and label realization timestamp t_{i,1} overlaps with the test fold if and only if:
max(t_{i,0}, T_{test,start}) <= min(t_{i,1}, T_{test,end})Purging operates symmetrically on both sides of a test fold:
- Left of the Test Fold (
t_{i,0} < T_{test, start}): A training observation that entered before the test fold must be purged if its exit timestamp extends into or beyond the test set (t_{i,1} >= T_{test, start}). Its outcome would otherwise inject future test price trajectory into the training objective. - Right of the Test Fold (
t_{i,0} > T_{test, start}): If test samples have labels that extend past the final test bar (T_{test, end} = max(t_{j,1})for alljin Test), any training sample that begins before those test labels have completely resolved (t_{i,0} <= T_{test, end}) must be purged.
Purging ensures that no single price tick is simultaneously utilized to evaluate a training label and an active test label.
2. Embargoing: Neutralizing Autoregressive Feature Memory
Even after all overlapping label intervals are purged, a secondary, subtler leakage vector remains: feature memory.
Quantitative features are rarely raw price bars; they are autoregressive transformations of historical price series:
- Exponential Moving Averages (EMA) with smoothing factor
alpha - Rolling volatility windows (e.g., 20-day standard deviation)
- Relative Strength Index (RSI), MACD, or Bollinger Band bandwidths
- Fractional differentiation filters with long memory weights
When training samples occur chronologically after a test fold, their input features X_{train} are calculated using price history that includes the test fold. For instance, if the test fold ends at bar 100, the 20-day moving average feature of a training sample at bar 105 is computed using prices from bars 86 through 105—fifteen of which occurred directly inside the test fold!
Test Fold: Bars 50 through 100
Candidate Train Sample at Bar 105:
  Feature: 20-period Rolling Mean
  Calculation Window: Bars 86 to 105
  Overlapping Test Bars in Feature: Bars 86 to 100 (15 bars!)
If the training algorithm optimizes weights on features that carry autoregressive memory of test-period volatility or trend structures, the model exploits information that violates out-of-sample purity.
Embargoing solves this asymmetry by discarding an additional buffer of training samples immediately following the test fold. The embargo interval begins at the conclusion of the test evaluation span (T_{test, end}) and extends forward in time by an embargo horizon h_{embargo}:
Embargo Boundary: t_{train,0} > T_{test,end} + h_{embargo}
where:
  h_{embargo} = ceil(N * embargo_pct)  or  h_{embargo} >= feature_lookback_memory
Because feature calculation only looks backward in time, an embargo is only necessary after a test fold, never before it. Prior to the test set, features cannot leak forward unless the engineer erroneously used future data in their feature calculation.
Structural Comparison: Standard K-Fold, Walk-Forward, Purged K-Fold, and CPCV
Systematic strategy validation requires balancing two opposing forces: temporal purity and statistical efficiency.
| Validation Strategy | Temporal Ordering Respected | Backtest Paths Generated | Variable-Duration Label Isolation | Autoregressive Memory Protection | Sample Utilization Efficiency | Primary Vulnerability |
|---|---|---|---|---|---|---|
| Standard K-Fold | No (Random shuffle) | 1 (Fragmented) | None | None | 100% | Severe temporal leakage; completely invalid for finance. |
| Walk-Forward (WFV) | Yes (Chronological) | 1 (Single historical path) | Only if custom dynamic purge applied | Inherent (train precedes test) | Low (Early folds train on small samples) | Evaluates only a single historical path; high metric variance. |
| Fixed-Gap TimeSeriesSplit | Yes (Sequential) | 1 (Sequential) | Partial (Fails if trade span exceeds gap) | Partial (Fixed buffer) | Moderate | Blind to dynamic volatility; fails on long-holding trades. |
| Purged K-Fold | Yes (Contiguous blocks) | 1 (Unified OOS coverage) | Complete (Exact dynamic purging) | Complete (Post-test embargo buffer) | High (~75% - 85% after purge/embargo) | More complex indexing; requires exact label end dates. |
| Combinatorial Purged CV (CPCV) | Yes (Grouped blocks) | C(K, N) Synthetic Paths | Complete (Exact dynamic purging) | Complete (Post-test embargo buffer) | High (Multiple train/test combinations) | Computationally demanding; requires combinatorial path generation. |
Purged K-Fold vs. Traditional Walk-Forward Validation
Novice quants often assume that traditional sequential Walk-Forward Validation (WFV) is sufficient for all financial machine learning. While WFV avoids training on the future, it has significant statistical limitations:
- Single Historical Path: Walk-forward testing evaluates the model along exactly one sequential timeline. If that historical sequence experienced a specific macroeconomic regime (e.g., an unusual 10-year bull market), the out-of-sample performance metric reflects that path alone.
- High Estimator Variance: Because the out-of-sample testing window is traversed only once, the estimated Sharpe ratio or Profit Factor has wide confidence intervals.
- Unequal Training Set Sizes: Early test folds in expanding walk-forward splits are evaluated using models trained on very small datasets, skewing performance downwards.
Purged K-Fold divides the timeline into K contiguous blocks, treating each block as an out-of-sample test set while training on the remaining K - 1 blocks (with purging and embargoing applied). This enables researchers to test across multiple regimes while maintaining strict statistical independence.
Furthermore, Combinatorial Purged Cross-Validation (CPCV) expands Purged K-Fold by selecting N test blocks out of K total partitions (C(K, N) combinations). This allows quantitative researchers to generate dozens of distinct out-of-sample equity curves and directly compute the Probability of Backtest Overfitting (PBO).
Production-Grade Python Implementation: PurgedKFold
Below is a complete, self-contained Python implementation of PurgedKFold engineered to comply with the scikit-learn cross-validation interface.
The class accepts sample indices alongside a label_end_times series containing the exact realization timestamp for each observation. It dynamically computes purge boundaries, applies post-test embargo buffers, and provides an algorithmic assertion function that validates zero temporal contamination.
"""
purged_cv.py: Production-grade Purged and Embargoed Cross-Validation.
Designed for financial time-series with variable-duration labels.
"""

from typing import Generator, Tuple
import numpy as np
import pandas as pd


class PurgedKFold:
    """
    Purged and Embargoed K-Fold Cross-Validation for financial machine learning.

    Parameters
    ----------
    n_splits : int, default=5
        Number of contiguous chronological folds.
    label_end_times : pd.Series
        Series indexed by observation start time (t0) containing the
        corresponding label realization timestamp (t1).
    embargo_pct : float, default=0.01
        Percentage of total observations to exclude immediately following
        the test fold to account for autoregressive feature memory.
    """

    def __init__(
        self,
        n_splits: int = 5,
        label_end_times: pd.Series = None,
        embargo_pct: float = 0.01,
    ) -> None:
        if n_splits < 2:
            raise ValueError(f"n_splits must be at least 2, got {n_splits}")
        if label_end_times is None:
            raise ValueError("label_end_times must be provided as a pd.Series.")

        self.n_splits = n_splits
        self.label_end_times = label_end_times
        self.embargo_pct = embargo_pct

    def get_n_splits(self, X=None, y=None, groups=None) -> int:
        return self.n_splits

    def split(
        self, X: pd.DataFrame, y=None, groups=None
    ) -> Generator[Tuple[np.ndarray, np.ndarray], None, None]:
        """
        Generate train and test indices with dynamic purging and embargoing.
        """
        n_samples = len(X)
        indices = np.arange(n_samples)

        # Align timestamps
        t0 = pd.to_datetime(X.index.values)
        t1 = pd.to_datetime(self.label_end_times.values)

        # Partition into contiguous chronological chunks
        chunk_size = n_samples // self.n_splits
        test_chunks = []
        for i in range(self.n_splits):
            start = i * chunk_size
            end = (i + 1) * chunk_size if i < self.n_splits - 1 else n_samples
            test_chunks.append(indices[start:end])

        embargo_bars = int(np.ceil(n_samples * self.embargo_pct))

        for test_idx in test_chunks:
            test_start_time = t0[test_idx[0]]
            # Test horizon extends to the latest label end time among test samples
            test_eval_end_time = np.max(t1[test_idx])

            # 1. Determine embargo horizon after the test evaluation period
            post_test_mask = t0 > test_eval_end_time
            post_test_indices = np.where(post_test_mask)[0]

            if len(post_test_indices) > 0:
                first_post_test_idx = post_test_indices[0]
                embargo_limit_idx = min(
                    n_samples - 1, first_post_test_idx + embargo_bars - 1
                )
                embargo_end_time = t0[embargo_limit_idx]
            else:
                embargo_end_time = test_eval_end_time

            train_mask = np.ones(n_samples, dtype=bool)

            # 2. Exclude test observations
            train_mask[test_idx] = False

            # 3. Purge left: training samples starting before test fold
            # whose labels extend into or beyond test start
            left_purge = (t0 < test_start_time) & (t1 >= test_start_time)
            train_mask[left_purge] = False

            # 4. Purge right: samples starting while test labels are resolving
            during_purge = (t0 >= test_start_time) & (t0 <= test_eval_end_time)
            train_mask[during_purge] = False

            # 5. Embargo right: samples starting within the autoregressive memory buffer
            embargo_purge = (t0 > test_eval_end_time) & (t0 <= embargo_end_time)
            train_mask[embargo_purge] = False

            train_idx = np.where(train_mask)[0]
            yield train_idx, test_idx


def assert_zero_leakage(
    train_idx: np.ndarray,
    test_idx: np.ndarray,
    t0: pd.DatetimeIndex,
    t1: pd.DatetimeIndex,
    embargo_delta: pd.Timedelta = pd.Timedelta(days=0),
) -> None:
    """
    Asserts zero temporal overlap between train and test intervals,
    and validates that train samples respect post-test embargo buffers.
    """
    test_start = t0[test_idx[0]]
    test_eval_end = np.max(t1[test_idx])

    for tr in train_idx:
        s_tr, e_tr = t0[tr], t1[tr]

        # Test mathematical interval intersection:
        # Overlap exists iff max(s1, s2) <= min(e1, e2)
        if max(s_tr, test_start) <= min(e_tr, test_eval_end):
            raise AssertionError(
                f"Purge Failure! Train sample index {tr} spanning [{s_tr} to {e_tr}] "
                f"intersects with Test evaluation window [{test_start} to {test_eval_end}]."
            )

        # Post-test embargo check
        if s_tr > test_eval_end and s_tr < test_eval_end + embargo_delta:
            raise AssertionError(
                f"Embargo Failure! Train sample index {tr} at {s_tr} "
                f"falls within post-test embargo window ({test_eval_end} to "
                f"{test_eval_end + embargo_delta})."
            )
Empirical Audit: Stress-Testing Leakage Across Three Splitters
To demonstrate the real-world impact of label overlap, we construct a synthetic test harness:
- Generate 200 daily financial bars with realistic price trends.
- Formulate dynamic triple-barrier labels with variable holding periods spanning 1 to 14 business days.
- Evaluate three splitting architectures:
- Architecture A: Naive
KFoldwithout shuffling. - Architecture B: Sequential
TimeSeriesSplitwith a static 5-bar gap. - Architecture C: Dynamic
PurgedKFoldwith a 2% post-test embargo.
- Architecture A: Naive
- Execute
assert_zero_leakageto record the exact count of temporal boundary violations.
"""
leakage_audit.py: Benchmarking leakage across financial splitters.
"""

import numpy as np
import pandas as pd
from purged_cv import PurgedKFold, assert_zero_leakage

# 1. Synthesize realistic daily market price series
np.random.seed(42)
n_bars = 200
dates = pd.date_range("2025-01-01", periods=n_bars, freq="B")

price_returns = np.random.normal(loc=0.0003, scale=0.015, size=n_bars)
prices = 100.0 * np.exp(np.cumsum(price_returns))
df = pd.DataFrame({"close": prices}, index=dates)

# 2. Simulate variable-length triple barrier holding periods (1 to 14 days)
holding_durations = np.random.randint(1, 15, size=n_bars)
end_dates = pd.Series(
    [dates[min(i + h, n_bars - 1)] for i, h in enumerate(holding_durations)],
    index=dates,
    name="label_end_time",
)

t0_arr = pd.to_datetime(df.index.values)
t1_arr = pd.to_datetime(end_dates.values)

print("=" * 65)
print("FINANCIAL CROSS-VALIDATION LEAKAGE BENCHMARK")
print(f"Total Observations: {n_bars} bars | Max Label Span: 14 bars")
print("=" * 65)


def audit_splitter(name: str, split_generator):
    total_leaks = 0
    fold_details = []

    for fold, (train_idx, test_idx) in enumerate(split_generator):
        leaks = 0
        test_start = t0_arr[test_idx[0]]
        test_end = np.max(t1_arr[test_idx])

        for tr in train_idx:
            s_tr, e_tr = t0_arr[tr], t1_arr[tr]
            if max(s_tr, test_start) <= min(e_tr, test_end):
                leaks += 1

        total_leaks += leaks
        fold_details.append((fold, len(train_idx), len(test_idx), leaks))

    print(f"\nResults for Splitter: {name}")
    print(f"{'Fold':<6} {'Train Count':<14} {'Test Count':<12} {'Overlapping Leaks':<18}")
    print("-" * 55)
    for fold, n_tr, n_te, lk in fold_details:
        print(f"{fold:<6} {n_tr:<14} {n_te:<12} {lk:<18}")
    print(f"Total Contaminated Training Samples: {total_leaks}")
    return total_leaks


# -------------------------------------------------------------------------
# Splitter A: Naive K-Fold (Contiguous chunks, no purge, no embargo)
# -------------------------------------------------------------------------
def naive_kfold(n_samples: int, n_splits: int = 5):
    indices = np.arange(n_samples)
    chunk = n_samples // n_splits
    for f in range(n_splits):
        te = indices[f * chunk : (f + 1) * chunk if f < n_splits - 1 else n_samples]
        tr = np.setdiff1d(indices, te)
        yield tr, te

audit_splitter("Naive K-Fold (No Purge)", naive_kfold(n_bars, n_splits=5))

# -------------------------------------------------------------------------
# Splitter B: Sequential Walk-Forward with Static 5-Bar Gap
# -------------------------------------------------------------------------
def fixed_gap_split(n_samples: int, n_splits: int = 5, gap: int = 5):
    chunk = n_samples // n_splits
    for f in range(1, n_splits):
        te = np.arange(f * chunk, min((f + 1) * chunk, n_samples))
        tr_end = max(0, f * chunk - gap)
        tr = np.arange(0, tr_end)
        yield tr, te

audit_splitter("Sequential Walk-Forward (Static 5-Bar Gap)", fixed_gap_split(n_bars, 5, gap=5))

# -------------------------------------------------------------------------
# Splitter C: PurgedKFold with Dynamic Purging and 2% Embargo
# -------------------------------------------------------------------------
pkf = PurgedKFold(n_splits=5, label_end_times=end_dates, embargo_pct=0.02)
audit_splitter("PurgedKFold (Dynamic Purge + 2% Embargo)", pkf.split(df))
Execution Output and Analysis
When this benchmark is executed in Python, the output illuminates the stark differences in data purity:
=================================================================
FINANCIAL CROSS-VALIDATION LEAKAGE BENCHMARK
Total Observations: 200 bars | Max Label Span: 14 bars
=================================================================

Results for Splitter: Naive K-Fold (No Purge)
Fold   Train Count    Test Count   Overlapping Leaks
-------------------------------------------------------
0      160            40           10
1      160            40           19
2      160            40           20
3      160            40           19
4      160            40           7
Total Contaminated Training Samples: 75

Results for Splitter: Sequential Walk-Forward (Static 5-Bar Gap)
Fold   Train Count    Test Count   Overlapping Leaks
-------------------------------------------------------
1      35             40           4
2      75             40           5
3      115            40           5
4      155            40           2
Total Contaminated Training Samples: 16

Results for Splitter: PurgedKFold (Dynamic Purge + 2% Embargo)
Fold   Train Count    Test Count   Overlapping Leaks
-------------------------------------------------------
0      146            40           0
1      137            40           0
2      136            40           0
3      137            40           0
4      153            40           0
Total Contaminated Training Samples: 0
Why Naive and Fixed-Gap Approaches Fail the Audit
- Naive K-Fold Leakage (75 Leaks): In Naive K-Fold, 75 out of the total training allocations were actively contaminated by price movements occurring within the test fold. In Fold 2 alone, 20 training observations had label spans crossing into the test boundary. A model trained under this setup peeks directly into the out-of-sample period, guaranteeing artificial predictive performance.
- Fixed-Gap Failure (16 Leaks): Even with a 5-bar static gap, 16 training observations leaked across the boundary because market volatility stretched position holding times up to 14 bars. A fixed gap only protects trades whose duration is shorter than the gap (
h <= 5). Whenever a position remains open during a sustained trend or consolidation, the static gap is breached. - PurgedKFold Perfection (0 Leaks): PurgedKFold eliminated every instance of temporal overlap while retaining an average of 142 clean training observations per fold. The out-of-sample metrics produced under this split represent authentic statistical generalizations.
Visualizing Fold Topology: ASCII Partitioner Map
To inspect the structural composition of each fold, we can render an ASCII matrix displaying the timeline. Below is the fold allocation matrix for a 50-bar subsample partitioned into 5 folds with variable-length labels and a 2-bar post-test embargo:
Cross-Validation Topology Map (Bars 1 to 50):
Legend:  [T] Clean Train  |  [*] Out-of-Sample Test  |  [P] Purged Label  |  [E] Embargo Buffer

Fold 0: [****************] [PPPP] [EE] [TTTTTTTTTTTTTTTTTTTTTTTTTTTT]
Fold 1: [TTTT] [PPPPPP] [****************] [PPPP] [EE] [TTTTTTTTTTTT]
Fold 2: [TTTTTTTTTTTT] [PPPPPP] [****************] [PPPP] [EE] [TTTT]
Fold 3: [TTTTTTTTTTTTTTTTTTTT] [PPPPPP] [****************] [PPPP] [EE]
Fold 4: [TTTTTTTTTTTTTTTTTTTTTTTTTTTT] [PPPPPP] [****************]
Notice the asymmetric architecture:
- Prior to the test block
[*], a purged zone[P]removes training samples whose exit boundaries spill into the test set. - Following the test block
[*], a dual shield is established: an initial purged zone[P]handles residual test label realization, followed immediately by an embargo buffer[E]neutralizing autoregressive feature memory.
Integrating Purged Cross-Validation into OpenBacktesting Research
In systematic quantitative development, machine learning cross-validation should never be combined directly with order execution logic in a single monolithic script. Doing so creates brittle pipelines where execution assumptions distort statistical model evaluation.
The professional workflow decouples research into two distinct phases:
- Signal Research & Out-of-Sample Calibration (Purged Cross-Validation): Evaluate feature importance, tune hyperparameters, and validate probability calibration across purged out-of-sample folds.
- Deterministic Order Simulation (OpenBacktesting Engine): Feed the calibrated out-of-sample predictions into OpenBacktesting's event-driven, bar-by-bar engine (
v0.2.1) to inspect realistic fills, transaction costs, and portfolio drawdowns.
flowchart TD
    subgraph Phase1["Phase 1: Isolated Signal Modeling"]
        OHLCV["Historical OHLCV Data"] --> Feat["Causal Feature Pipeline<br/>(Lags, Volatility, Regimes)"]
        Feat --> Label["Triple Barrier Labeling<br/>(t0 entry, t1 exit)"]
        Label --> PKF["PurgedKFold Splitter<br/>(Purging + Embargo)"]
        PKF --> MLFit["Model Training & OOS Predictions"]
    end

    subgraph Phase2["Phase 2: OpenBacktesting Engine (0.2.1)"]
        MLFit --> OOS_Signals["Out-of-Sample Trade Signals"]
        OOS_Signals --> Engine["OpenBacktesting Bar-by-Bar Engine"]
        Engine --> ExecSim["Order Matching & Fills<br/>(Commissions, Slippage)"]
        ExecSim --> SQLite["SQLite Trial Persistence"]
        SQLite --> Studio["OpenBacktesting Studio UI<br/>(Inspect Orders, Trades, Equity)"]
    end
Feeding Purged Predictions into OpenBacktesting
Once out-of-sample probabilistic signals are generated via purged cross-validation, they are mapped into discrete trading actions and executed sequentially inside OpenBacktesting.
The following Python script illustrates how clean out-of-sample signals integrate into an OpenBacktesting research script:
"""
openbacktesting_ml_strategy.py: Executing purged ML signals in OpenBacktesting.
Requires Python >=3.12,<3.15 and openbacktesting 0.2.1.
"""

import pandas as pd
from openbacktesting.core import Strategy, Engine
from openbacktesting.models import OrderType, SignalEvent


class PurgedMLSignalStrategy(Strategy):
    """
    Strategy consuming pre-computed, out-of-sample predictions generated
    via Purged and Embargoed Cross-Validation.
    """

    def __init__(self, signals: pd.Series, threshold: float = 0.65) -> None:
        super().__init__()
        self.signals = signals
        self.threshold = threshold

    def on_bar(self, bar) -> None:
        current_time = bar.timestamp

        # Guard: Check if we have an out-of-sample signal for current bar
        if current_time not in self.signals.index:
            return

        prob_up = self.signals.loc[current_time]
        position = self.get_position(bar.symbol)

        # Rule 1: High-conviction bullish signal -> Enter Long
        if prob_up >= self.threshold and position.quantity == 0:
            target_qty = int(self.portfolio.cash / bar.close * 0.95)
            if target_qty > 0:
                self.order(
                    symbol=bar.symbol,
                    quantity=target_qty,
                    order_type=OrderType.MARKET,
                    tag="ML_ENTRY_LONG",
                )

        # Rule 2: Conviction drops or flips bearish -> Close Position
        elif prob_up < 0.50 and position.quantity > 0:
            self.order(
                symbol=bar.symbol,
                quantity=-position.quantity,
                order_type=OrderType.MARKET,
                tag="ML_EXIT_SIGNAL",
            )


# Example execution workflow:
if __name__ == "__main__":
    # Assume 'oos_predictions' was computed via PurgedKFold
    # Load historical OHLCV data
    # data = pd.read_parquet("btc_usdt_daily.parquet")
    # engine = Engine(data=data, initial_capital=100000.0, commission=0.0005)
    # strategy = PurgedMLSignalStrategy(signals=oos_predictions, threshold=0.60)
    # result = engine.run(strategy)
    # result.save_trial_to_sqlite("trials.db")
    pass
Inspectability and SQLite Trial Persistence
OpenBacktesting (0.2.1) enforces an inspectable research ethos. Every backtest run persists complete, tick-accurate artifact trails to local SQLite databases:
- Order Audit Trail: Verify that every order timestamp strictly matches or succeeds the out-of-sample signal timestamp.
- Fill Price Accuracy: Confirm whether orders were executed at next-bar Open rather than same-bar Close, ensuring execution-level temporal purity.
- OpenBacktesting Studio Inspection: Open the local web UI (
openbacktesting studio) to interactively scrub through the equity curve, examine drawdown underwater periods, and overlay entry/exit tags directly atop historical candlesticks.
When your underlying cross-validation pipeline utilizes dynamic purging and embargoing, and your backtesting engine enforces bar-by-bar causal execution, you bridge the gap between theoretical quantitative research and realistic performance.
Cross-Validation Audit Checklist for Systematic Researchers
Before committing capital to any machine learning or algorithmic trading strategy evaluated via cross-validation, verify your research pipeline against this engineering checklist:
- Exact Label Horizon Tracking: Does your feature matrix store explicit realization timestamps (
t_{i,1}) for every observation, rather than assuming fixed bar lengths? - Dynamic Pre-Test Purging: Are training observations whose label realization timestamps extend into or beyond
T_{test, start}completely removed from the training fold? - Dynamic Post-Test Purging: If test sample labels resolve after the test fold concludes (
t_1 > T_{test, end}), are training samples within that resolution span purged? - Post-Test Embargo Buffer: Is an embargo buffer enforced immediately following the test set to account for autoregressive feature lookback memory (EMAs, rolling volatility, RSI)?
- Algorithmic Leakage Assertion: Does your CI/CD test suite execute an automated assertion (
assert_zero_leakage) confirming zero interval intersections across all folds? - Feature Calculation Precedes Splitting: Are all feature calculations strictly backward-looking (
shift(1)) to ensure contemporaneous bar closes do not leak into execution prices? - Scaling Fitted on Training Folds Only: Are normalization scalers (
StandardScaler,MinMaxScaler) fitted exclusively on the purged training set, never on the global dataset? - Combinatorial Backtest Verification: If evaluating strategy robustness, have you generated multiple out-of-sample paths via Combinatorial Purged Cross-Validation (CPCV) to inspect the distribution of Sharpe ratios?
Summary and Next Steps
Standard cross-validation fails in finance because market data violates the i.i.d. premise through overlapping label windows and autoregressive memory:
- Overlapping Labels Create Future Leakage: Financial labels span holding intervals
[t_{i,0}, t_{i,1}]. When a training label's horizon crosses into a test fold, the training objective peeks directly into future test price trajectory. - Fixed Gaps Are Insufficient: Static splitting buffers fail to protect variable-length exit events generated by the Triple Barrier Method during high-volatility or prolonged consolidation regimes.
- Purging and Embargoing Provide Dual Shielding: Purging eliminates overlapping label windows on both sides of a test fold, while embargoing neutralizes post-test autoregressive feature memory.
- Purged K-Fold Delivers Statistical Power: Unlike sequential walk-forward validation which evaluates only a single historical trajectory, Purged K-Fold provides full out-of-sample coverage across diverse macroeconomic regimes without temporal contamination.
To deepen your understanding of causal strategy validation, explore our comprehensive technical guides on Backtesting Machine Learning Signals Without Data Leakage, Walk-Forward Optimization in Python, and Quantifying the Probability of Backtest Overfitting.